GPU cluster deployment and build-up consultation

We size, deploy and run AI capacity — on-premises, cloud or hybrid.

From our delivered H200 project
960NVIDIA H200 GPUs
45 daysorder to production
~4×training throughput

What we do

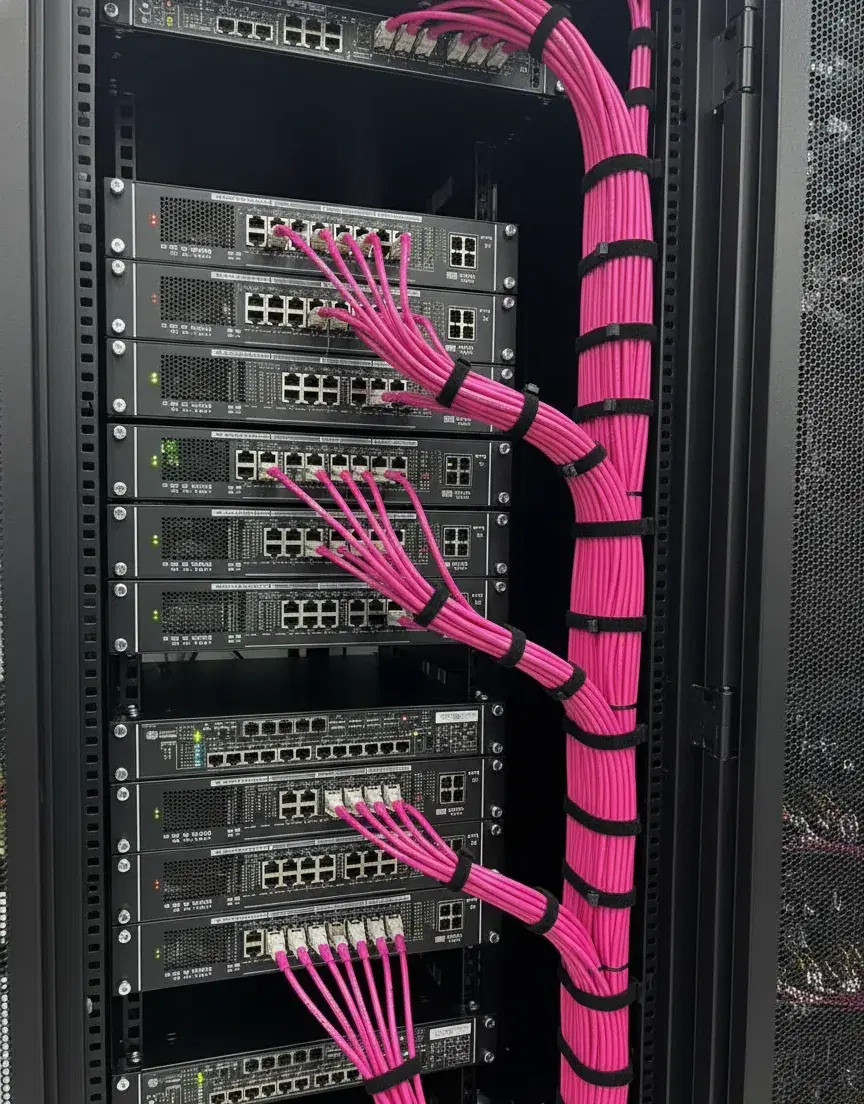
Network fabric cabling in a GPU rack

Sizing and architecture

GPUs, fabric, storage, power and cooling, sized to your workloads.
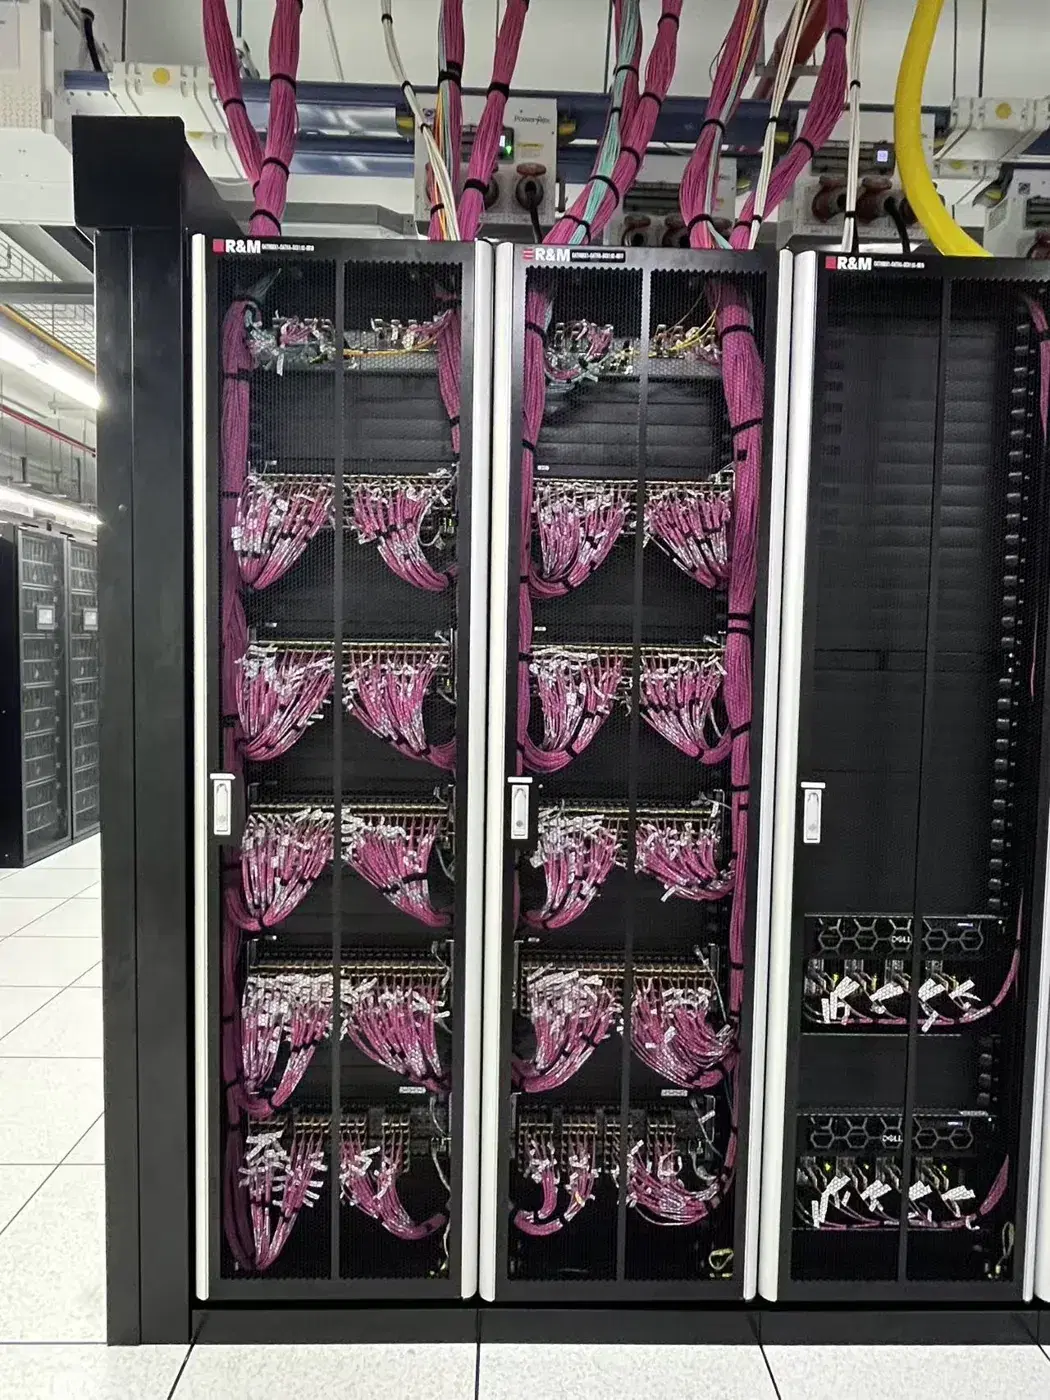
GPU racks with purple network cabling

Deployment and operations

Racked, commissioned, orchestrated and run — or handed to your team.
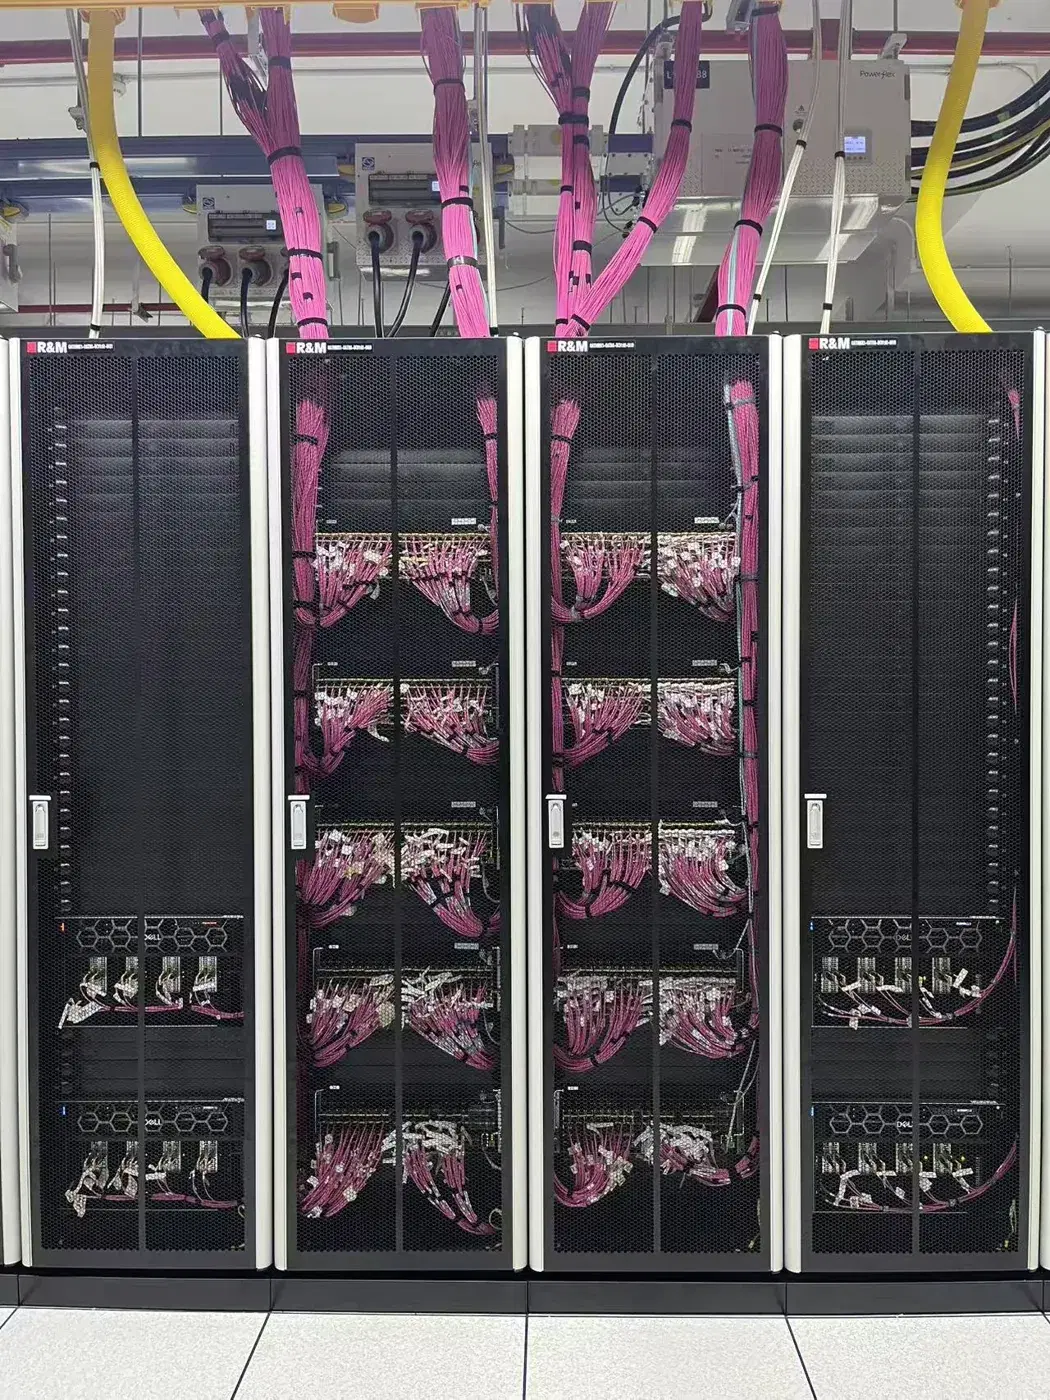
The 960-GPU H200 cluster
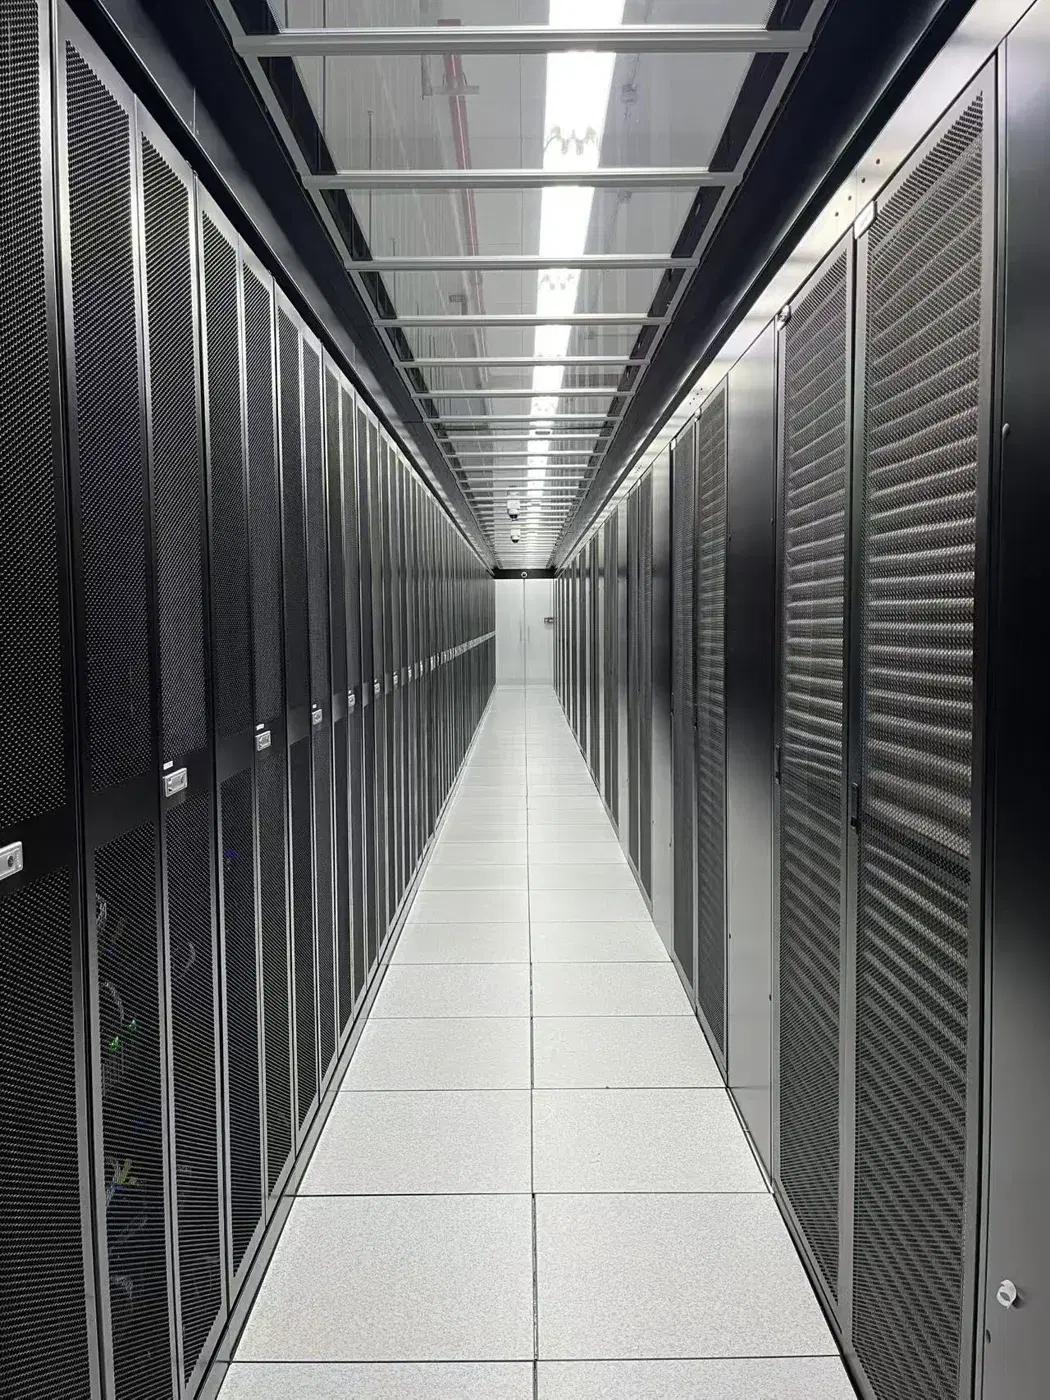
Inside the H200 cluster aisle
400 GbE RoCEv2 fabric
Delivered project

960 NVIDIA H200 GPUs, production in 45 days

A GPU cluster our team co-designed and delivered for a customer in Thailand.

128GPU server nodes
3.2 Tbpsper node, RoCEv2
2 → 4 PBstorage, no downtime
~4×training throughput
14 dhardware
10 drack & cable
17 dmigrate
12 dcommission
21 dexpand storage
45 days from purchase order to production.
Read the case study

How an engagement runs

01AssessWorkloads, constraints, budget, timeline.
02DesignReference architecture and bill of materials.
03DeliverRack, commission, migrate, tune.
04Operate or hand overRunbooks and training, or managed operations under SLA.

Standing up AI capacity?

Tell us your workloads. We will come back with a sizing and a plan.

Discuss a deployment