
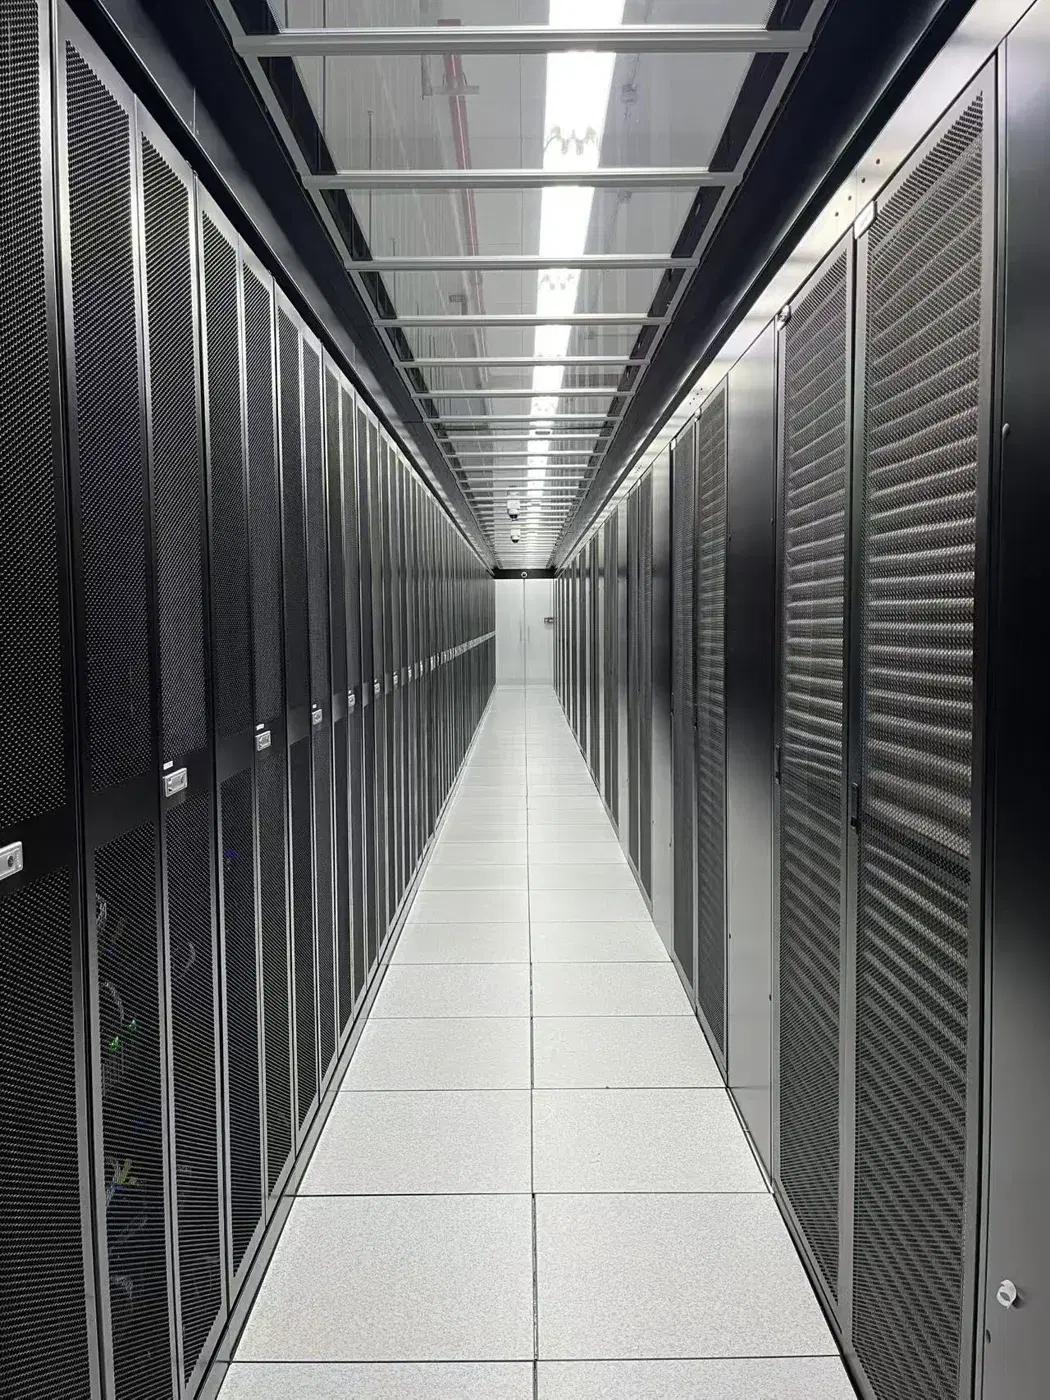
Delivered project · Thailand
960 NVIDIA H200 GPUs, production in 45 days
Our team designed and delivered a 128-node GPU supercluster for one of Asia’s fastest-growing AI video generation platforms.
960H200 GPUs
128GPU server nodes
45 daysorder to production
3.2 Tbpsper node
The brief
The customer’s H100 environment could no longer train fast enough to keep up with product releases. They needed an H200 supercluster at a scale not yet delivered in Thailand — in weeks, not months.
01
Train next-generation text-to-video and multimodal models
02
Migrate petabyte-scale datasets with zero data loss
03
Reach state-of-the-art training speed and scaling
04
Go live end to end in under 45 days
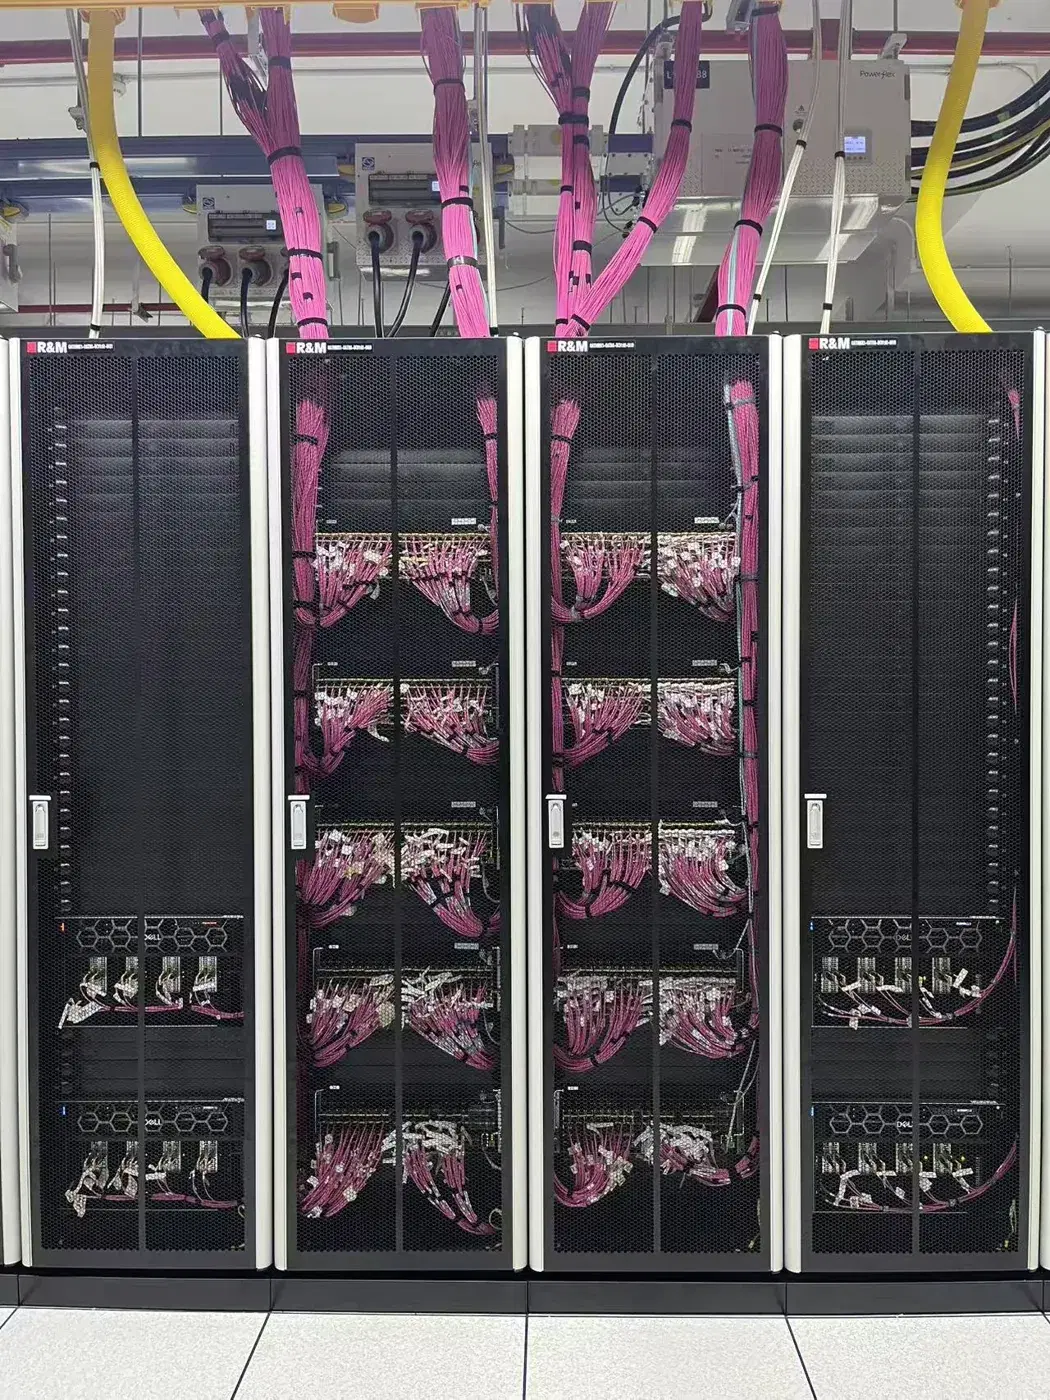
The 128-node H200 supercluster in production
What our team delivered
128 GPU servers960 NVIDIA H200 GPUs, racked and commissioned.
8-rail 400 GbE RoCEv2 fabric3.2 Tbps per node, 1:1 non-blocking.
High-performance parallel storageSub-120 µs latency, expanded live from 2 PB to 4 PB.
Multi-domain architectureCompute, storage, management and boundary security.
GPUDirect RDMA, GPU–NIC 1:1Full training efficiency on every node.
Tuned NCCL + UCX stackLossless distributed training at scale.
45 days, phase by phase
0114 daysHardware deliveryDespite global GPU supply constraints
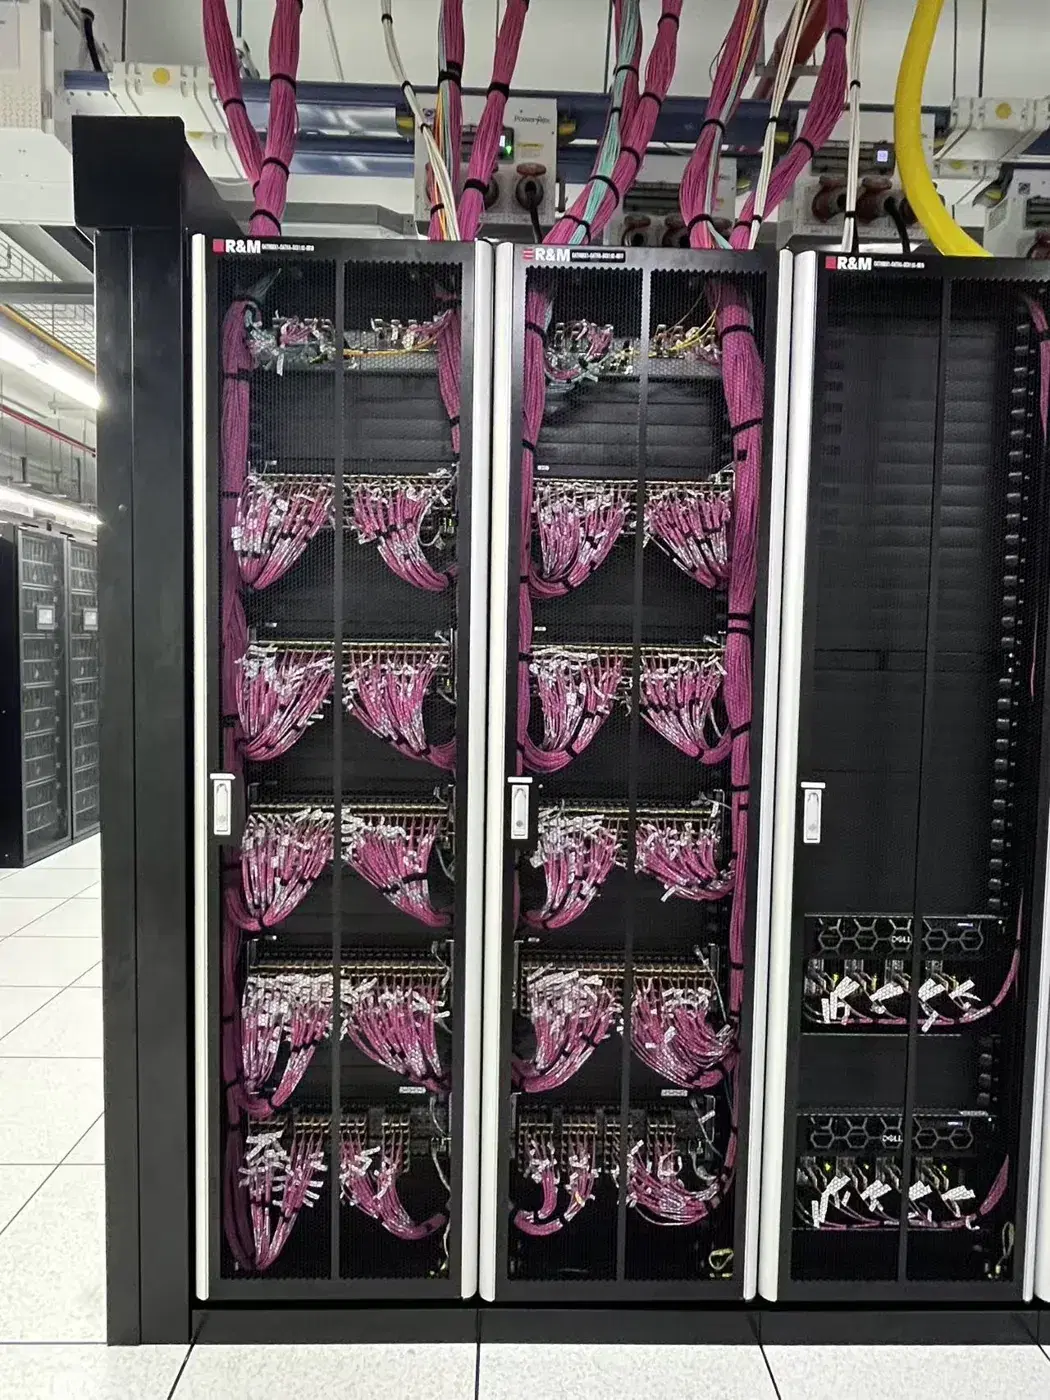
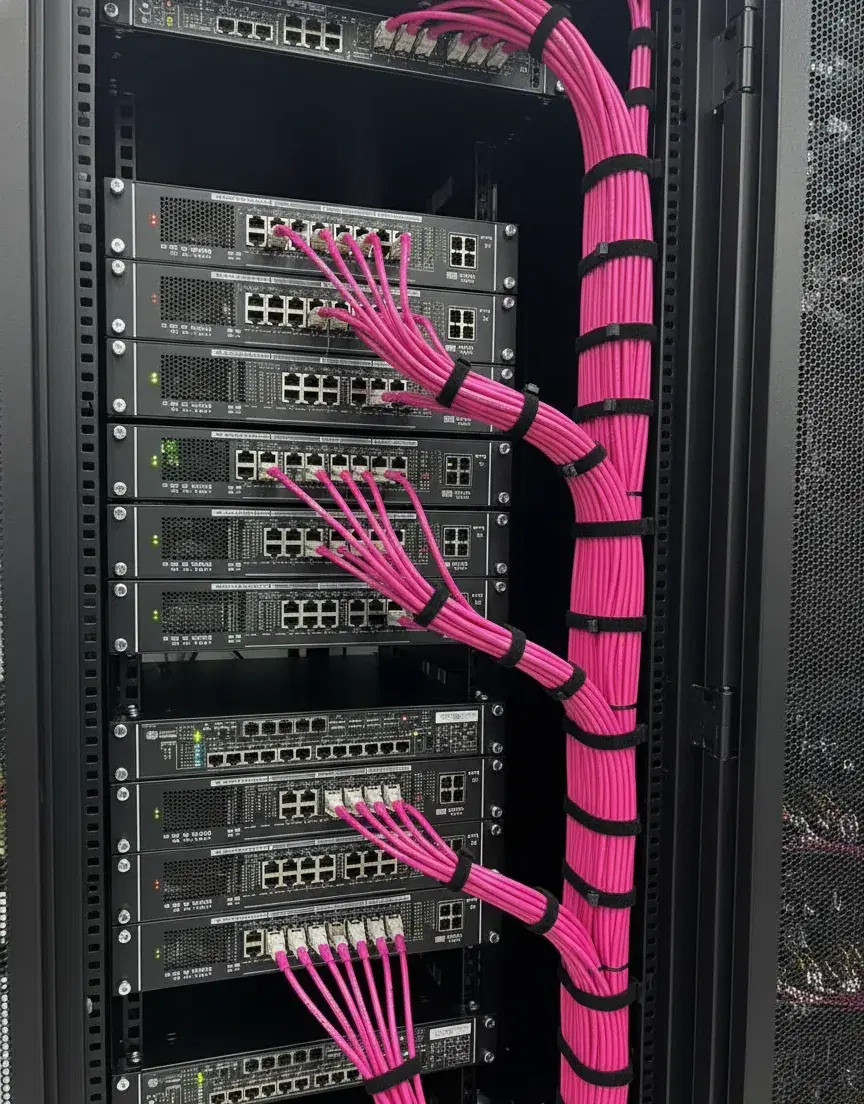
0210 daysRacking & cabling3,000+ cables, 0.1% error rate
033 + 14 daysData migrationOn-prem and overseas, multi-PB
0412 daysCommissioningCompute, storage, NCCL and fabric tuning
0521 daysStorage expansion2 PB → 4 PB, no service interruption
The results
~4×faster end-to-end training
369.6 GB/sNCCL AllReduce
310 GiB/sstorage read · 11.6M IOPS
0packet loss under load
BeforeAfter
Training bottlenecked by H100 limits~4× faster end-to-end training
Long iteration loops, slow releasesNew model versions every week
Scaling limited to 256 GPUsNear-linear scaling to 960 GPUs
“What normally takes 4–6 months was executed in 45 days — without compromise.”
Planning a GPU cluster?
Tell us your workloads. We will come back with a sizing and a plan.